-
Originally aired Thursday, May 28th, 2026
Stop reacting to "unexpected" failures. Start seeing what is actually happening before they occur.
Conveyor failures rarely begin with a breakdown.
They develop quietly - through friction, misalignment, bearing wear, and electrical stress - long before alarms fire or operations stop.
In most facilities, these early signals go undetected until they show up as:
- Throughput loss
- Jam escalation
- Operator callouts
By the time a problem is visible, the impact is already underway.
In this session, we’ll break down how conveyor degradation develops across high-throughput environments - and why traditional monitoring approaches consistently detect issues too late.
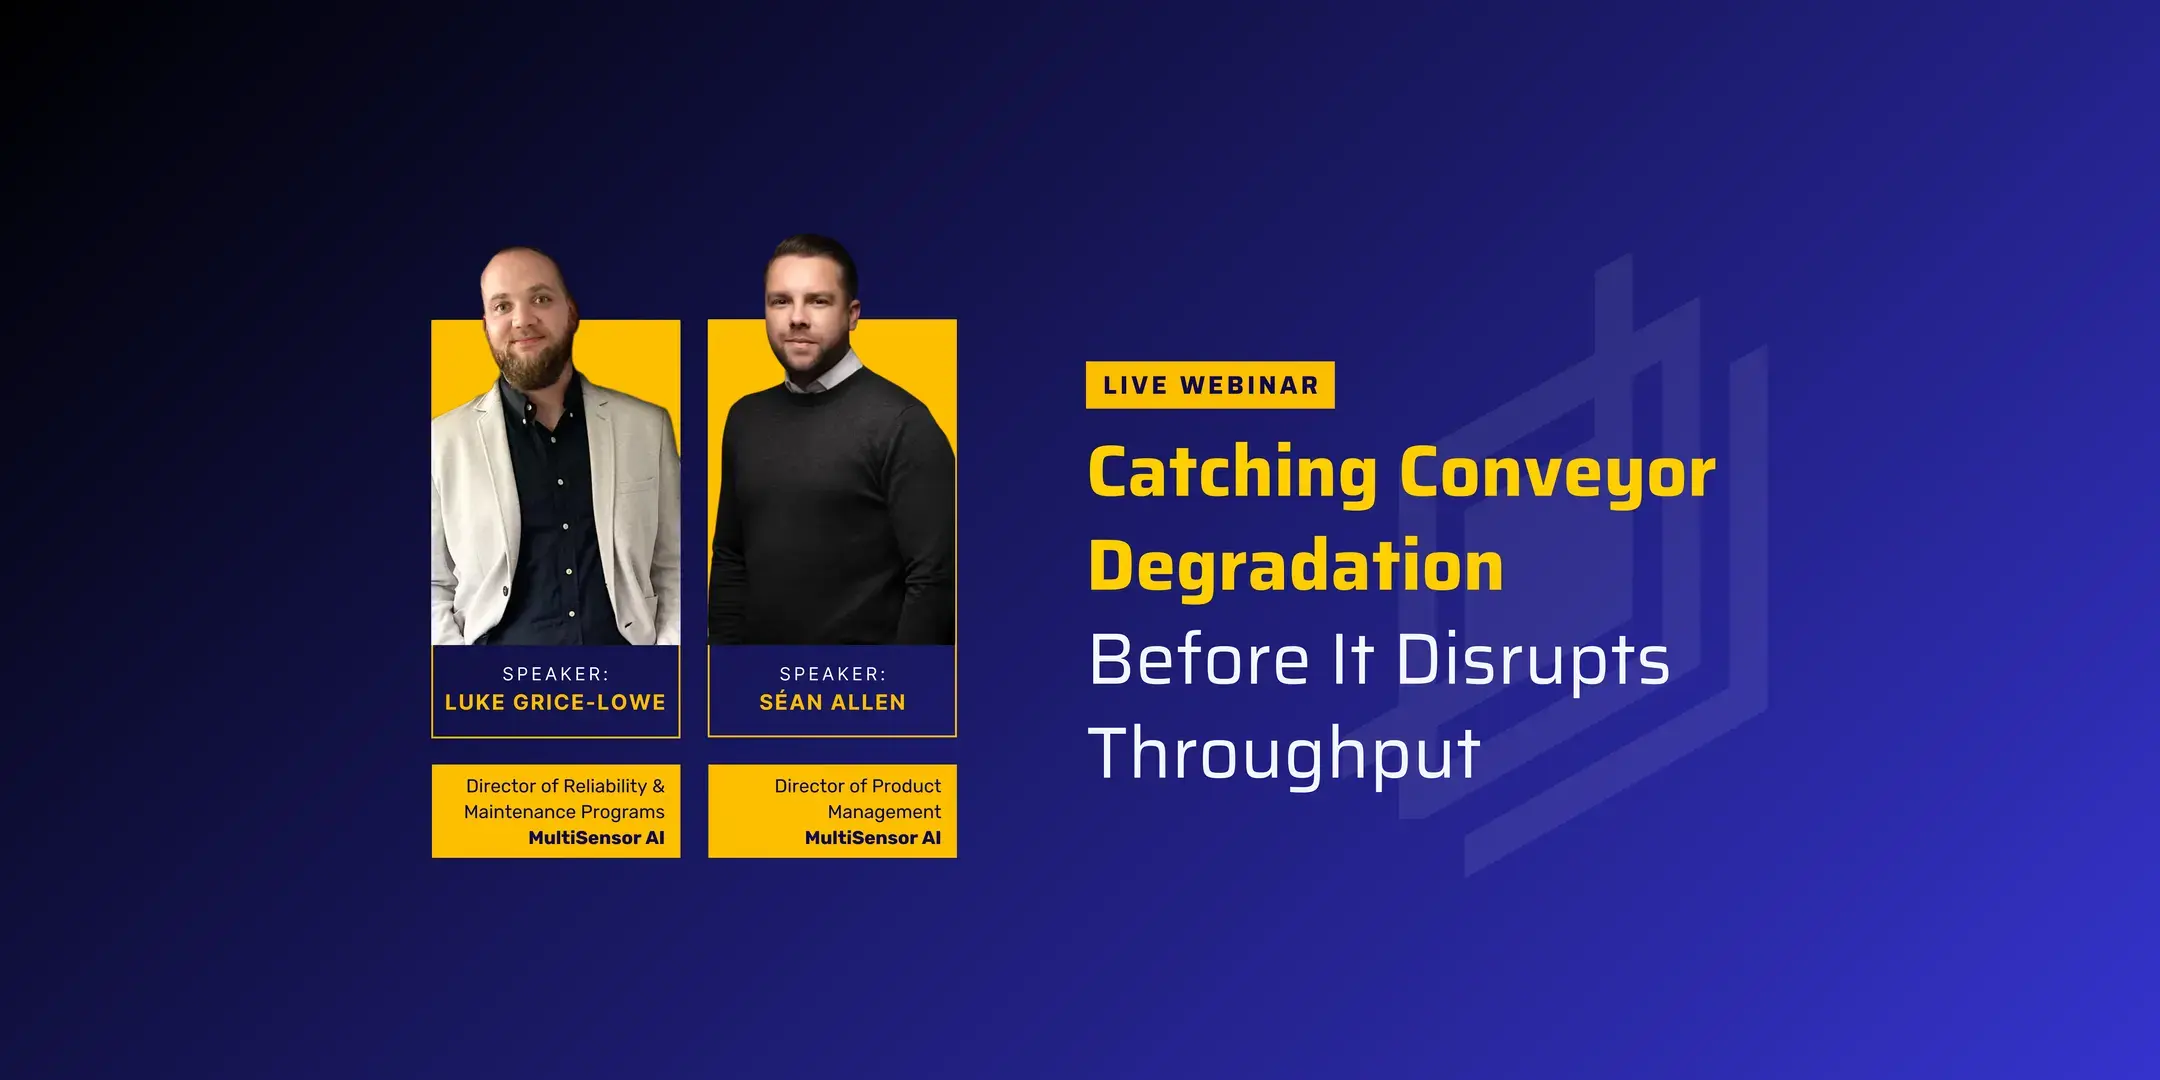
This session will be led by Luke (Director of Reliability & Maintenance Programs) and Sean Allen (Director of Product Management) - both former Amazon reliability leaders who have operated and scaled maintenance and reliability programs across large, automation-heavy networks.
Drawing on real-world experience across hundreds of sites, they’ll explore not just how failures develop - but why they’re often missed, including the operational, engineering, and program-level factors that contribute to late detection.
What You’ll Learn
- Why conveyor failures feel sudden - but aren’t
- Where degradation starts across belts, bearings, rollers, and drives - including how installation, maintenance practices, and component quality play a role
- Why inspections, SCADA, and alarms miss early-stage issues - and how “state monitoring” differs from degradation detection
- How program design decisions - from PM strategies to asset criticality - influence what gets detected (and what gets missed)
- How “non-critical” issues quietly erode throughput, OEE, and SLA performance
- What changes when teams detect degradation earlier - from reactive firefighting to controlled, planned intervention
Who Should Attend
This session is designed for leaders responsible for uptime, throughput, and reliability in automation-heavy environments:
- Operations leaders
- Reliability / RME teams
- Maintenance leaders
- Controls & automation teams
Speakers
- Luke - Director of Reliability & Maintenance Programs, MultiSensor AI
Former Amazon reliability leader responsible for scaling maintenance and reliability programs across large, high-throughput operations. Leads global implementations of early detection strategies across automation-heavy environments.
- Séan Allen - Director of Product Management, MultiSensor AI
Former Amazon Global MHE Reliability Manager, responsible for reliability strategy across 1,200+ sites and ~900,000 assets.
Now leads product strategy at MultiSensor AI, translating real-world failure patterns into scalable detection frameworks.